Success storyAI & data
Context-aware SQL generation
Turning plain-English business questions into SQL people can actually trust — by giving a language model the schema, the vocabulary, and a reviewer.
- LLMs
- SQL
- Metadata
- Human review
Data & analytics · AI/ML · Data strategy
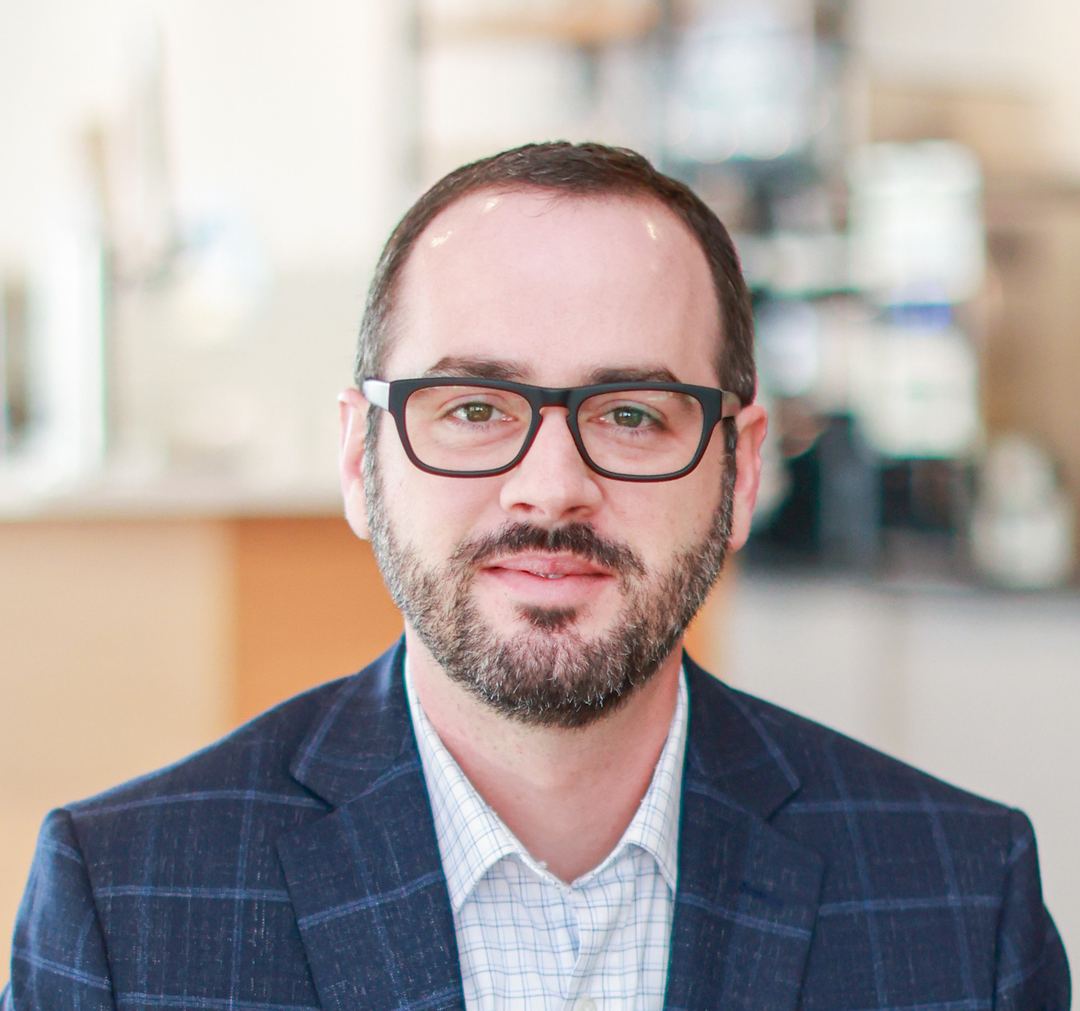
I'm a data and analytics leader in Virginia Beach — Director, Data & Analytics at Catalight, and founder of Fruitful Intelligence, my data science consultancy. I've spent my career turning payments, healthcare, tax, and public-sector data into models, platforms, and decisions, and teaching graduate data analytics along the way. This is where I write, experiment, and keep the side projects my GitHub keeps promising to finish.
Personal: email meBusiness & contracting: SoFruitful.com
📍 Virginia Beach, VA
Selected work
Turning plain-English business questions into SQL people can actually trust — by giving a language model the schema, the vocabulary, and a reviewer.
Cutting repetitive manual checks and inconsistent calls in document validation — with OCR, field-level checks, confidence signals, and a human for the hard cases.
A desktop app for early-stage data modeling: load a CSV, explore distributions and correlations, plot, and train and compare scikit-learn models without writing a notebook.
Hands-on experiments in scaling and tuning gradient boosting classifiers on a public health-indicators dataset, written up as a blog post with code on GitHub.
Recent writing
Beer
A five-gallon Mosaic IPA experiment, an enthusiastic fermentation, and a beer that tasted suspiciously like a stout.
Data Science · Development
Large language models (LLMs) represent the next generation of artificial intelligence applications, attaining widespread attention and adoption. These models demand substantial energy and resources for training. Consequently, there has been a shift towards developing pre-trained models like bidirectional encoder representations from transformers (BERT), utilizing millions of parameters from training texts to create general use models. An evolution of this approach involves fine-tuning models with domain-specific data, enhancing their utility in fields such as medicine, law, and science.
Data Science
Gradient boosting classifier models are a powerful type of machine learning algorithm that outperform many other types of classifiers. In simplest terms, gradient boosting algorithms learn from the mistakes they make by optmizing on gradient descent. A gradient boosting model values the gradient descent, or the direction of the steepest increase of a function, to make adjustments so that the function can increase rapidly over each iteration. Gradient boosting models can be used for classfication or regression. This post will concern itself with gradient boosting classification. In particular, we will study and optimize three gradient boosting models, AdaBoost (sklearn), XGBoost, and Gradient Boosting Classifier (sklearn). We will study these classifiers with the Kaggle data set, Kaggle: Diabetes Health Indicators Dataset . In particular, we will use the binary data set. I will not be doing any cleansing or engineering of the data. I am strictly experimenting with the effects of the learning rate and number of estimators hyperparameters on gradient boosting model performance.
Data Science
Forecasting remains an indispensable tool for businesses to make informed decisions about future trends, demands, and opportunities. Accurate forecasts can lead to better resource allocation, inventory management, and strategic planning. When it comes to forecasting, data scientists have many tools at their disposal, ranging from traditional and time-tested methods to advanced artificial intelligence (AI) techniques. While AI methods have gained significant attention in recent years, traditional forecasting methods like Moving Average, Exponential Moving Average, and Linear Regression Forecasting still hold their ground in many real-world scenarios. As a data scientist with substantial experience in machine learning and big data analytics, I will shed light on why, in most cases, traditional forecasting methods remain preferable to their more advanced counterparts.
Off the clock
I consider myself a generalist who's always chasing the next recreational coding project. Away from the keyboard, you'll usually find me outside or elbow-deep in a hobby. More about me →
Get in touch
Personal
Questions about a post, a side project, a good IPA recommendation, or something you're building — my inbox is open.
Email mesteven.ray.purcell@gmail.com
Business & contracting
Consulting, contracting, and other business inquiries go through Fruitful Intelligence LLC, my separate company site — not this personal inbox.
Visit SoFruitful.com ↗